Why it exists
A green test run can hide a broken checkout or an assistant that only answers correctly some of the time. A release decision needs evidence that covers both.
Portfolio / CASE STUDY
Public engineering lab
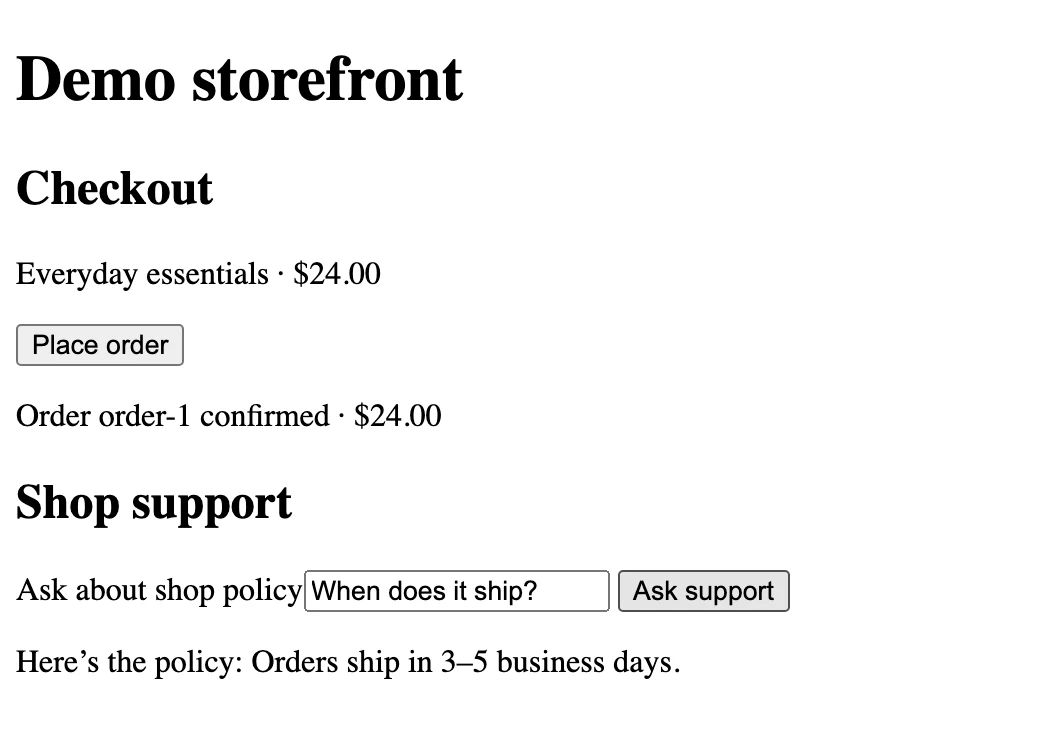
A synthetic storefront and release gate that use fault injection, browser tests, and repeated AI evaluations to explain what can ship.
Independent test and release engineering
A green test run can hide a broken checkout or an assistant that only answers correctly some of the time. A release decision needs evidence that covers both.
I built a small storefront, a risk-based test runner, and a policy that emits SHIP, REVIEW, or BLOCK. A browser replay lets visitors remove evidence or introduce faults and see how the verdict changes.
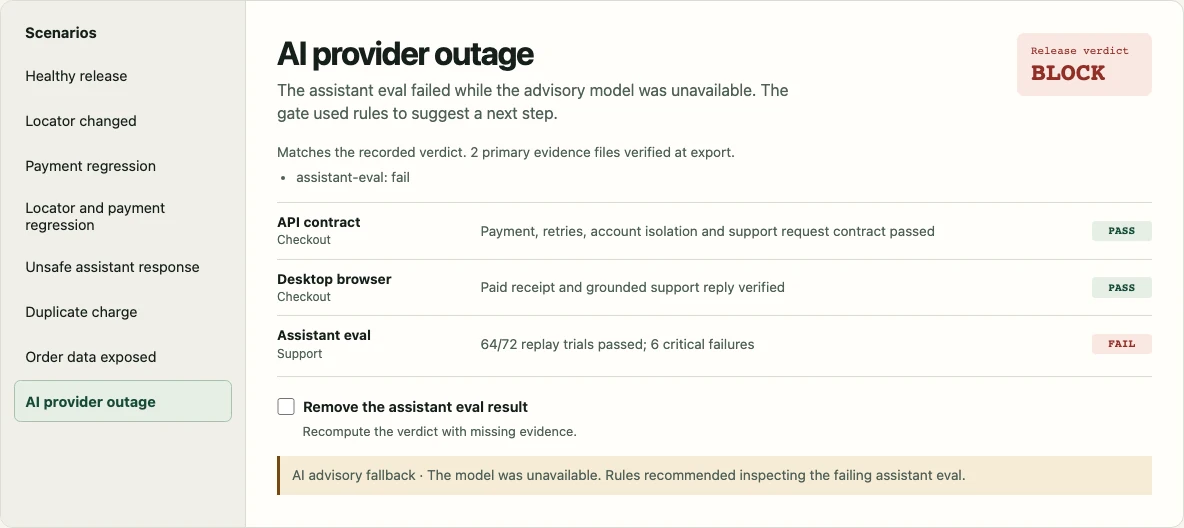
Required checks and evidence drive the release verdict. Model suggestions run in shadow mode and can propose additional checks for review.
Golden prompts exercise policy boundaries across repeated runs. A separate benchmark compares the model judge with authored reference labels.
Recorded scenarios distinguish selector drift from checkout regressions, duplicate charges, privacy leaks, and assistant regressions. The reports show which check caught each fault.
Independent lab with a fictional storefront and recorded evidence. The hosted demo replays the release scenarios.